Templates
Content Lake
Treat content as structured JSON documents with referential integrity. The database you need to drive content workflows in real-time.
Store any JSON in Content Lake, structured or unstructured. Make it instantly queryable. Define schemas when you need them and connect to any system with an API.
GROQ is our open-source query language for JSON. Query and reshape results with database-level precision. All without being forced into someone's generic API.
Content Lake maintains true referential integrity between content pieces. Build complex context graphs while ensuring that broken references never break your applications.
The database built for content
Content Lake stores any valid JSON document, with schemas living in your Sanity Studio configuration, not as database constraints. Evolve content models without migrations or downtime Import legacy content without prior modeling.
// In Sanity Studio: Define content models for your editorial interfaces
export default {
  name: 'product',
  type: 'document',
  fields: [
    {
      name: 'title',
      type: 'string',
      validation: Rule => Rule.required()
    },
    {
      name: 'category',
      type: 'reference',
      to: [{ type: 'category' }]
    }
  ]
}

// Meanwhile, Content Lake can store any valid JSON:
const document = {
  _id: 'custom-document',
  _type: 'anything',
  arbitraryField: 'No schema needed!',
  nestedData: {
    whatever: ['you', 'want'],
    counts: 42
  }
}
GROQ
GROQ is the perfect companion to a JSON-based datastore, letting you query content regardless of structure. Unlike GraphQL, which requires rigid schema definitions, GROQ works with whatever shape your data takes. Maintain referential integrity across your documents, ensuring you can confidently traverse relationships.
// Query across differently structured documents
*[_type in ["legacyPost", "article", "blogEntry"]] {
  title,
  // Safely access fields that might not exist in all documents
  "author": coalesce(authorName, author->name, "Unknown"),
  // Transform on the fly based on document structure
  "summary": select( defined(excerpt) => excerpt, defined(content) => pt::text(content)[0...150] + "...", "No summary available" ),
  // Gather related content regardless of reference field name
  "related": *[references(^._id)]
}
Mutations, Patches, Actions
Content Lake gives you multiple methods to modify content with precision. Create, replace, and delete documents with mutations. Make updates to specific fields with patches or manage publishing workflows with Actions.
// Make precise updates independent of schema constraints
client.patch('document-id')
  // Add fields that weren't in original schema
  .set({ newMetricField: 'value', 'deeply.nested.property': true })
  // Perform mathematical operations .inc({viewCount: 1})
  // Conditional mutations based on current state
  .ifRevisionID('previous-revision') // Array operations preserving referential integrity
  .append('relatedContent', [ {_type: 'reference', _ref: 'doc-123'} ])
  // Perform migrations on the fly
  .unset(['legacyField', 'deprecated.nested.field'])
  .commit({visibility: 'async'})
Perspectives
Switch between content states with a single parameter—viewing drafts as published, filtering unpublished changes, or creating layered views of multiple releases. Perfect for content preview, staging environments, and ensuring drafts don't leak into production
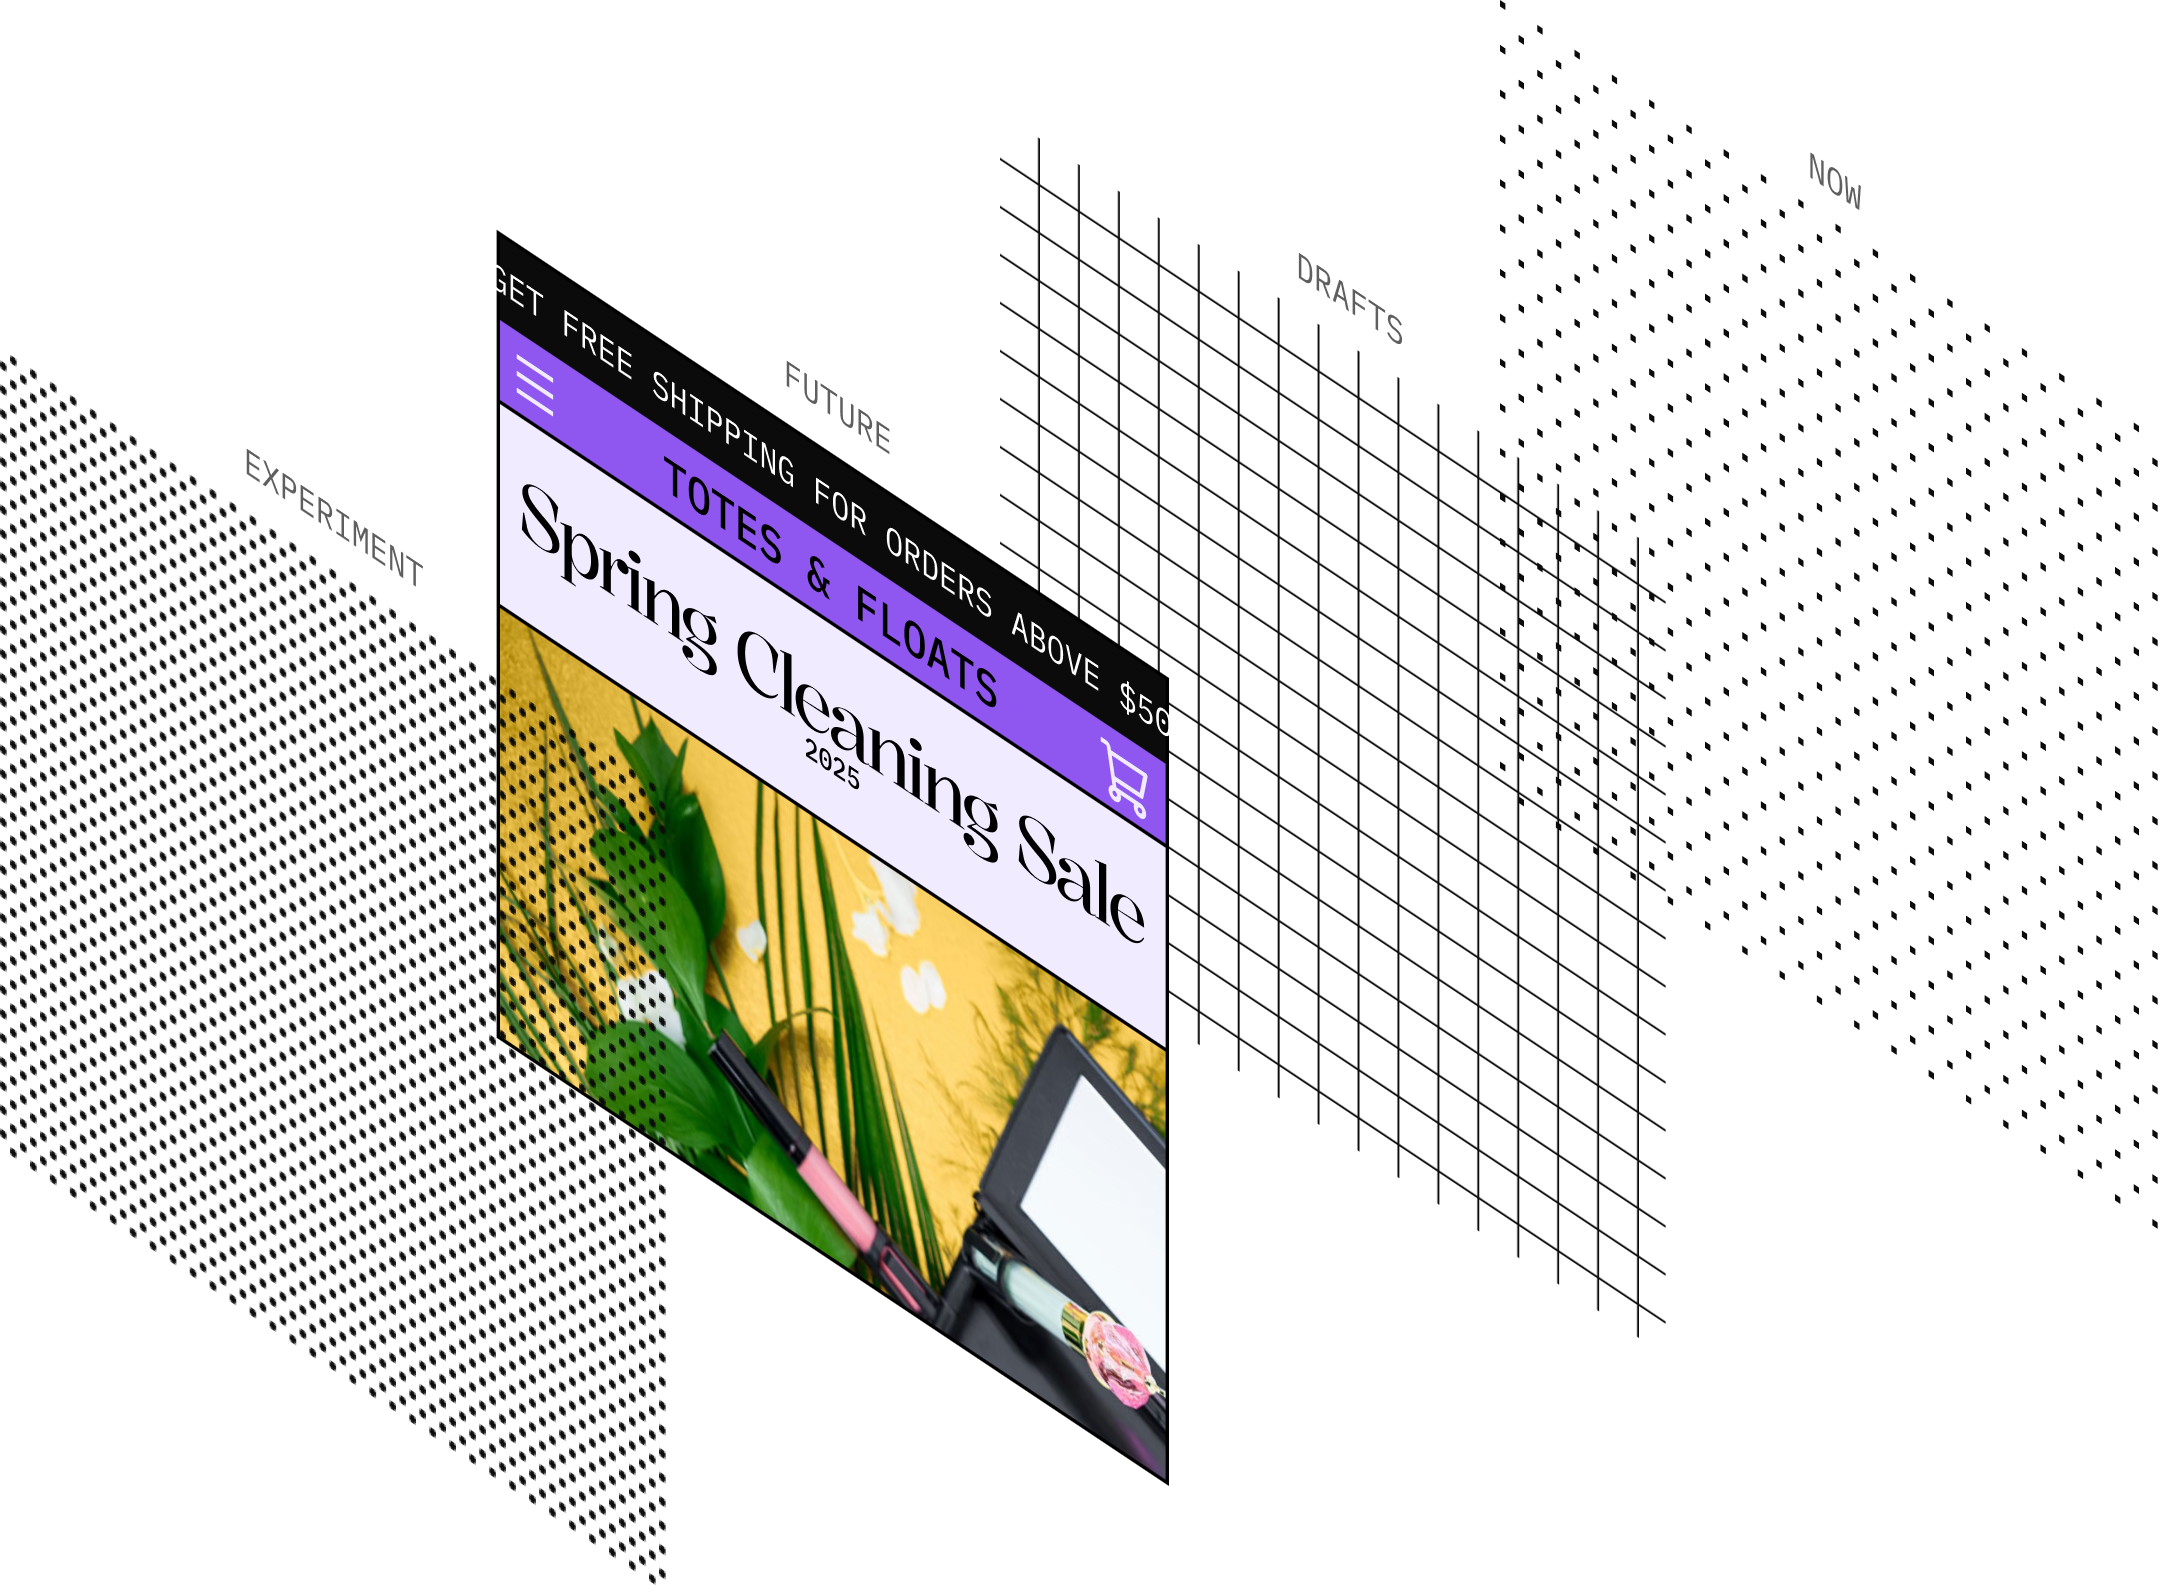
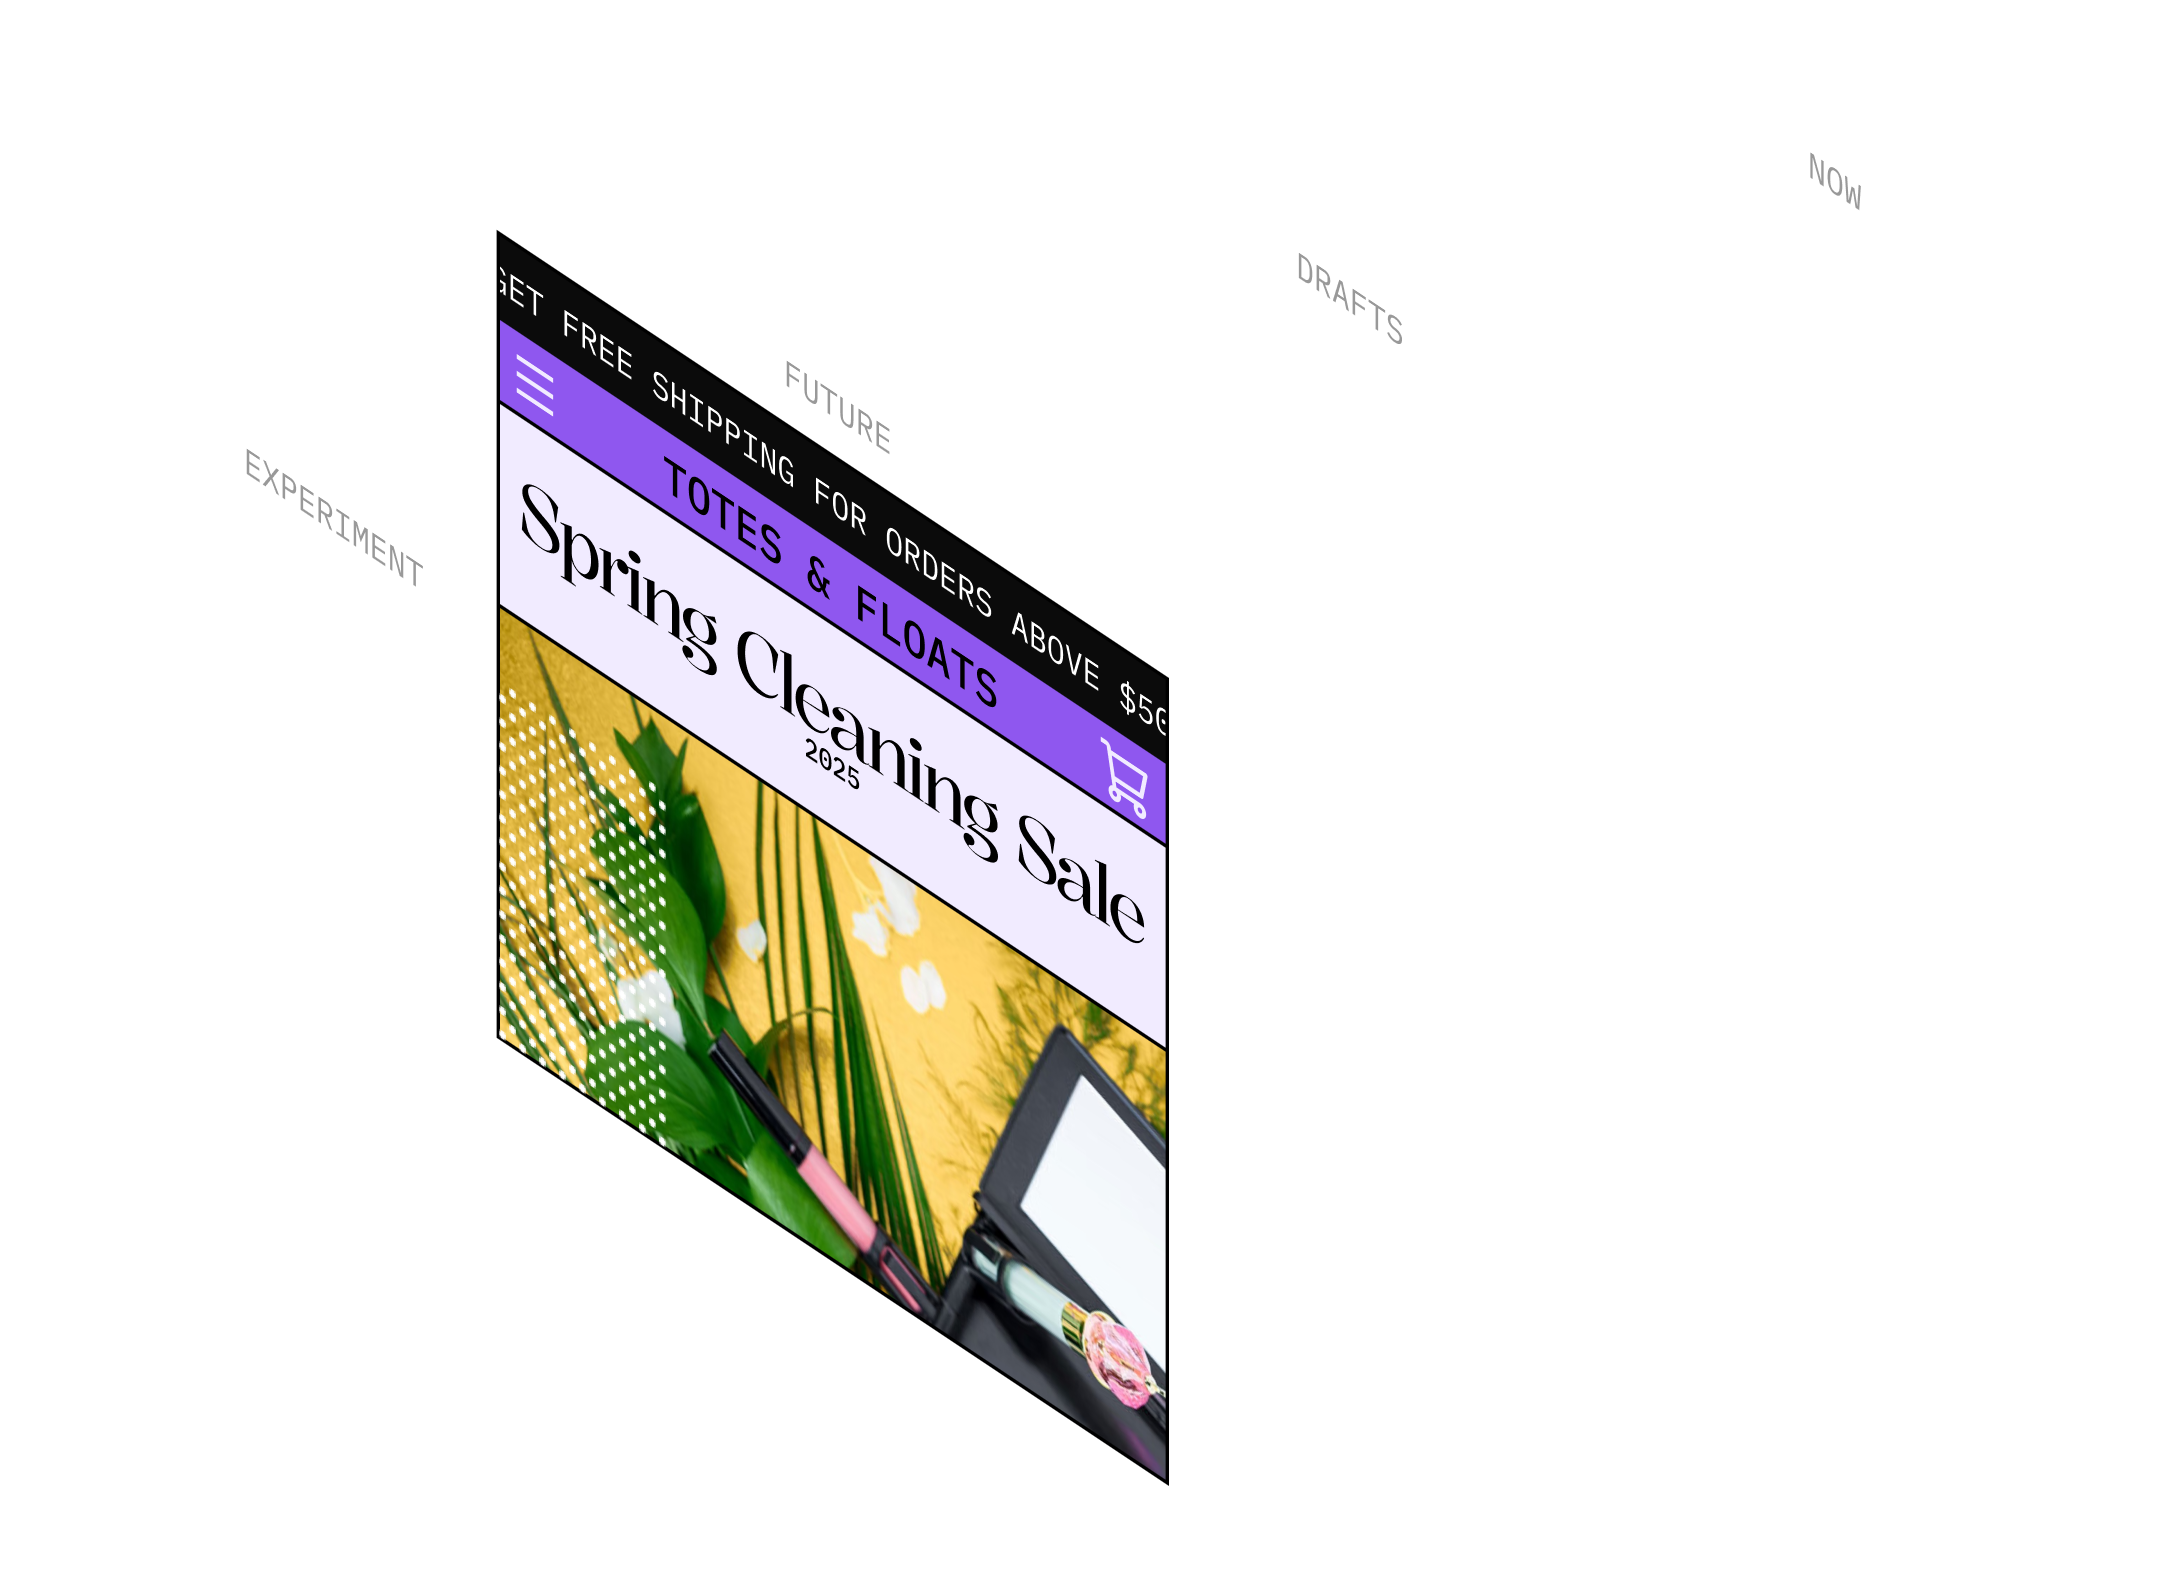
Content Lake becomes your organization's content hub, connecting previously isolated systems and ensuring consistent experiences across all customer touch-points—from websites to apps to in-store displays.
Group related changes into managed releases, preview exactly how they'll look together, and schedule precise publishing times—all without disrupting your regular content workflow.
Content Lake is the real-time content database that gives your team structured storage, granular mutations, and APIs to power everything from editorial workflows to downstream delivery.
We built separate Studios for editorial and ad workflows, but both run on the same Content Lake. That shared structure is what lets us move fast across teams and brands.

Nick Woodward
Director of Engineering, Morning Brew
Morning Brew
Sign up for Sanity for free and start crafting your first project.